02 / 04
An AI-native CRM that shows its uncertainty
Northstar is a working prototype of a goal-driven CRM for retention teams. I designed the journey from a stated goal to an audited action, then built it end to end as a React and TypeScript front end on synthetic data: 7 flows, 3 roles and 10 designed failure scenarios.
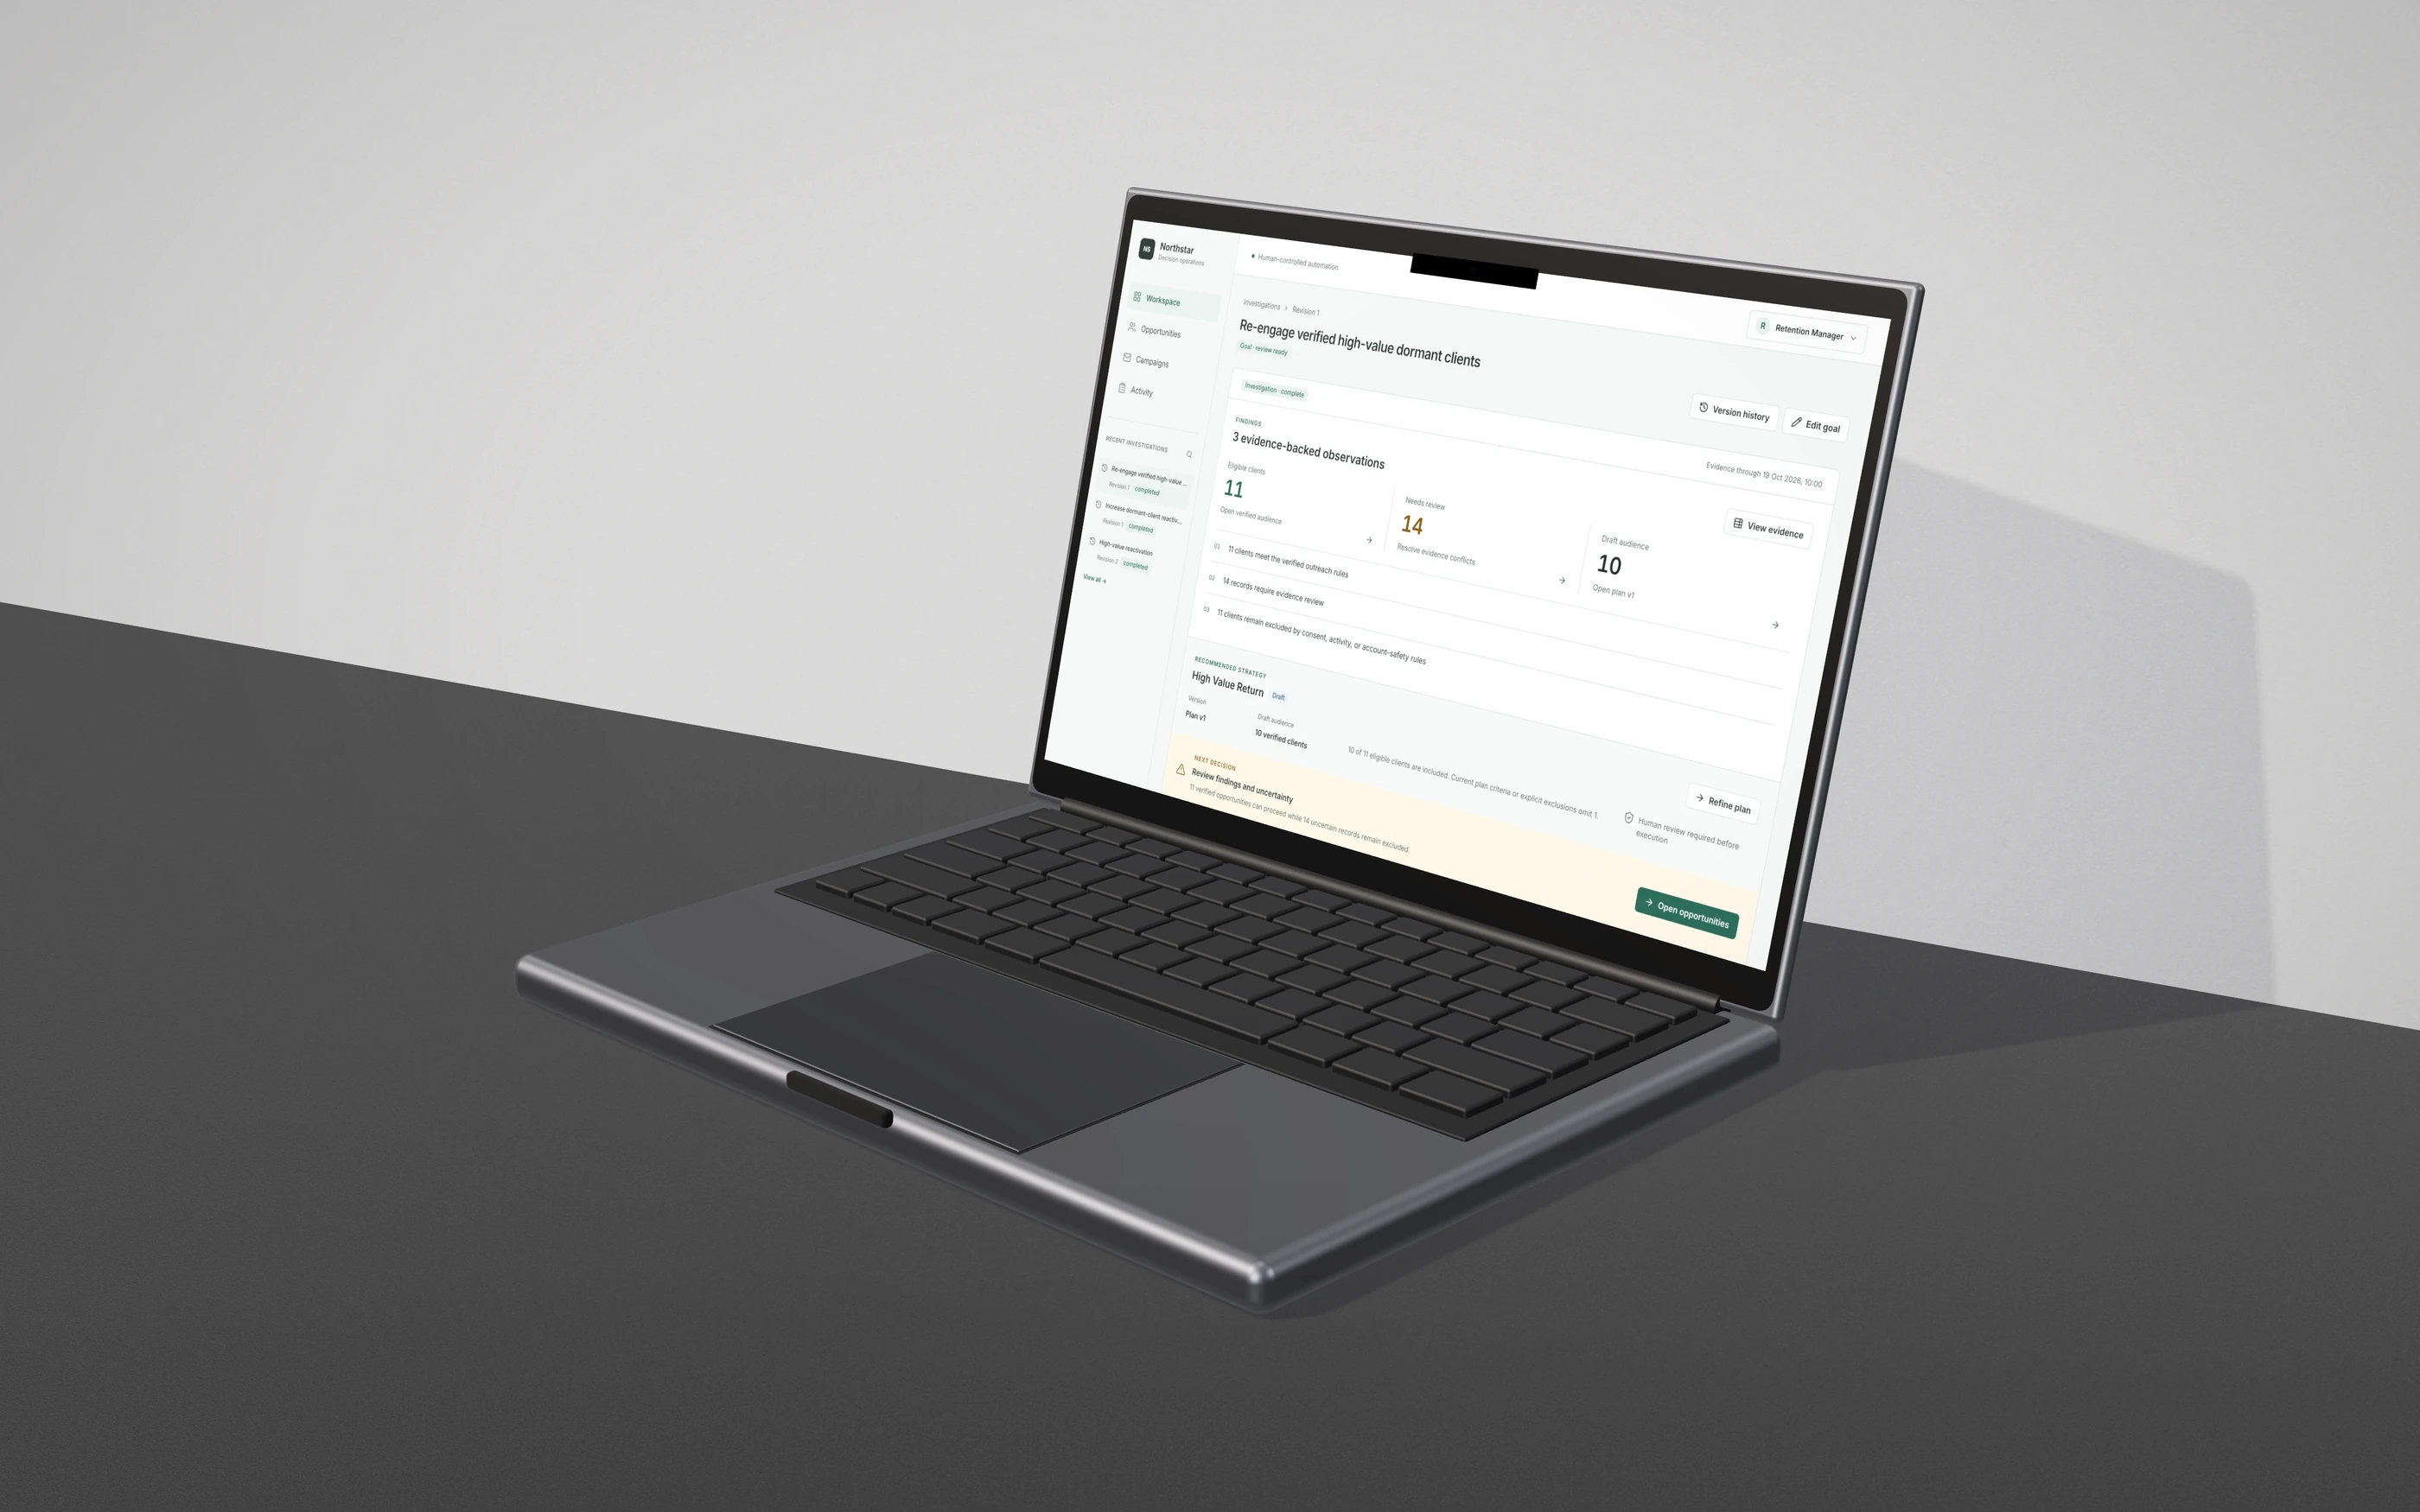
A CRM that stays honest about what its AI doesn't know
Retention teams reactivating dormant enterprise clients work in tools built around modules, not outcomes. The judgment that decides who gets contacted lives outside the system, in exports and spreadsheets, where nobody can audit it.
Northstar starts from a business outcome. The AI investigates and drafts, people keep authority over consequential decisions, and the handoffs between them are designed rather than left to chance.
the problem
A CRM asks which workflow you want. A retention team has a goal.
A retention manager doesn't want a dashboard. They want dormant enterprise clients to come back this month, without emailing someone who withdrew consent. In a traditional CRM, the judgment that decides who gets contacted lives outside the system, in exports and spreadsheets, where nobody can audit it.
Workflow-driven CRM
The user does the investigation.
The riskiest decisions happen where the system can't see them.
- Open the dormant-accounts dashboard (human)
- Build filters for inactivity and deposits (human)
- Export a report to a spreadsheet (human)
- Check consent in another system (gap)
- Decide who is “probably fine” (unrecorded)
- Send the campaign (irreversible)
Northstar
The user makes the decisions.
Each step leaves a record of who, or what, decided, and from which evidence.
- State the business goal (human)
- Investigate records against the goal (AI)
- Inspect evidence and resolve conflicts (uncertain)
- Refine the plan, preview its impact (human)
- Authorize one exact plan version (compliance reviewer)
- Execute, reconcile, retry safely (system)
research
While researching AI-native CRMs, I noticed a recurring pattern: a lot of attention goes into what AI can do, but less into helping users understand why it makes certain recommendations. The reasoning isn't always clear, conflicting information can be easy to miss, and users may not know when they're expected to act.
Northstar was designed to address these gaps. Every recommendation is grounded in traceable evidence, uncertainty and conflicting information are surfaced rather than silently resolved, and execution requires explicit, human approval. The goal wasn't simply to make AI more capable, but to make its decisions understandable, accountable, and safe to act on.
Design challenge
How might we turn CRM work from manual task execution into goal-driven, AI-assisted decisions, without giving up transparency, safety or human control?
the core idea
Most AI products design the answer. Northstar designs the space around it.
An AI that reaches a conclusion is the easy part. Trust breaks in the handoffs: between what the model concluded and what it actually saw, between what it knows and what it can't know, between a human's approval and what gets executed, and between a failed send and a safe retry. I treated these four seams as the product.
Seam 1 · AI reasoning
01
Show the evidence
“What did it actually look at?”
Findings link to the client records behind them. Evidence carries a freshness date. Every number opens its source.
Seam 2 · Uncertainty
02
Keep the unknown visible
“What doesn't it know?”
Conflicting or missing evidence becomes its own state. Uncertain consent is never treated as permission.
Seam 3 · Human decision
03
Bind approval to a version
“Who decided, on what, exactly?”
Edits create a new version. Approval covers one version. A change makes earlier reviews and approvals stale.
Seam 4 · Execution
04
Design the recovery
“What happened, and is it safe to retry?”
Completed, failed and unknown outcomes stay distinct. Unknowns are reconciled before retrying. Completed actions are never repeated.
classification · seam 2
Uncertain is a destination, not a rounding error
Every client record goes through the same questions. Only one path leads into an audience, and even that path ends at a person, not at a send.
Evidence present? No
Held · missing
Says what is missing; no conclusion drawn.
Sources agree? No
Held · conflict
Both records shown; a person resolves it.
Consent unknown
Held · review
Never treated as permission.
Consent withdrawn
Excluded
With the rule that excluded it.
Matches plan? No
Omitted
Eligible; fixed by refining the plan.
Matches plan? Yes
Draft audience
Still needs a human approval.
autonomy
Four kinds of action, decided before any prompt was written
Autonomy is a design property, not a model setting. I sorted every action in the journey into one of four groups, and the interface follows from that sorting. A button lives where its group says it may.
AI may do
Without asking
- Read CRM evidence against the goal
- Classify records as eligible, uncertain or excluded
- Draft a plan and outreach copy
- Calculate the impact of a proposed edit
AI does, then tells
With notification
- Investigation completed or stopped
- Plan version generated
- Evidence freshness and source gaps
- AI provider unavailable
Needs a person
With approval
- Resolving uncertain consent or eligibility
- Saving a changed plan version
- Authorizing a plan for execution
- Retrying an action whose outcome is unknown
Must never
Hard limits
- Treat unknown consent as permission
- Execute on a stale or unapproved version
- Answer follow-up questions without evidence to ground them
- Repeat an action that already completed
Retention Manager
- Set goals and run investigations
- Review opportunities and refine plans
- Request approval for a plan version
- Inspect evidence, plans and the audit log
Compliance Reviewer
- Authorize or return a plan version
- Inspect evidence, plans and the audit log
Viewer
- Inspect permitted items only
failure catalogue
Ten things that go wrong, designed before the happy path was finished
Each failure answers the same four questions in the interface: what happened, why, what is still safe, and what the user can do next. A failure that can't answer all four isn't designed yet.
Seam 2
Missing evidence
User sees which fact is missing, on the client record.
Still safe: no conclusion is drawn from the gap.
Next: held for review until the evidence arrives.
Seam 2
Conflicting evidence
User sees both records, labelled Conflict, with their sources.
Still safe: the AI never quietly chooses one.
Next: a person resolves the conflict on the record.
Seam 2
Uncertain consent
User sees “Held for review” in the plan status column.
Still safe: the client is excluded from every audience.
Next: human review before any outreach.
Seam 1
Invalid recommendation
User sees the rule the plan breaks, at the field.
Still safe: output is checked against business rules before display.
Next: correct or revise it as a new version.
Seam 3
Restricted permissions
User sees who can act, and how to hand off to them.
Still safe: review, approval and execution are blocked for that role.
Next: hand off to the right role.
Seam 3
Stale approval
User sees that the approval belongs to an earlier version.
Still safe: the changed plan cannot run on the old approval.
Next: request approval for the new version.
Seam 4
Failed execution
User sees exactly which actions failed.
Still safe: completed actions are left alone.
Next: a controlled retry of the failed actions only.
Seam 4
Unknown outcome
User sees “Unknown”, not a guess of sent or failed.
Still safe: no retry until the status is reconciled.
Next: reconcile the status, then decide.
Seam 1
AI provider unavailable
User sees “Grounded follow-ups are not available”, with the reason.
Still safe: no made-up answers to fill the gap.
Next: work continues from verified findings.
Seam 4
Duplicate action
User sees completed actions marked as skipped on retry.
Still safe: execution safeguards stop repeat sends.
Next: nothing to do. The record shows why.
recovery · seam 4
Ten sends. Eight complete, one failed, one unknown. Now what?
This is the run from the prototype's verification journey. The tempting design is a single “Retry” that sends to anyone not marked complete. That would resend to the unknown client, who may already have received the email. Northstar treats the three outcomes differently.
Outcomes reported
01
Keep three states, not two
8 completed, 1 failed, 1 unknown. “Unknown” is shown as it is. Showing it as failed invites a duplicate send. Showing it as sent hides a possible gap.
Reconcile
02
Resolve the unknown first
The unknown action's status is reconciled with the execution record before it can be retried.
Controlled retry
03
Retry only what failed
Safeguards on each action skip the eight completed sends. The retry covers only the failure, and the log records why each action was skipped.
Verified in the prototype: retrying did not duplicate the successful actions. The run used synthetic data and a simulated execution channel.
approval · staleness
An approval is a promise about one version. Edits break it, on purpose
Plan v1 is drafted: the AI proposes 10 verified clients. The compliance reviewer authorizes v1, by number. Then the manager excludes a client, and v1's approval no longer describes what would run. Plan v2 is a new version, impact is reviewed again and v1 stays in history, unchanged. Only an approval of v2 can release v2.
In the build, a plan that is awaiting approval can't be refined. The request must be withdrawn first, so nobody can change a plan while someone else is reviewing it.
trade-offs
Every safety rule costs some speed. These are the trades I chose
Chose
Outcome-first workspace
Over module navigation: contacts, deals, reports.
Cost: less familiar to people used to classic CRMs, who expect a module menu.
Chose
Evidence before recommendation
Over a confident one-line answer.
Cost: more to read before acting. Every number links to its source to keep that short.
Chose
Visible uncertainty
Over a cleaner list that hides 14 open questions.
Cost: the product looks less finished. That's accurate, so it stays.
Chose
Exact-version approval
Over approving “the campaign”.
Cost: small edits need re-approval. Impact review makes each one quick to judge.
Chose
Disabled follow-ups when ungrounded
Over a chat box that always answers.
Cost: the feature can look missing. The disabled state explains why.
Chose
Persistent decision threads
Over disposable AI conversations.
Cost: more structure to model, but findings, plans and approvals stay linked to their investigation.
Chose
Bounded execution
Over end-to-end automation.
Cost: slower than a fully automated send, and more explainable when something goes wrong.
limits & next
What this is, and what it isn't yet
Still a prototype. The data is 36 invented clients built to exercise eligible, uncertain and excluded paths, and execution is simulated: no real email was sent and no live CRM or provider was connected. The design reasoning comes from the problem framing, not from studies with retention or compliance teams, and nothing here measures reactivation, conversion or time saved.
Next: test the journey with real retention managers and compliance reviewers and watch where they hesitate at each seam. Measure time to a trusted decision, not clicks saved. Learn which conflicts teams resolve fastest and which they escalate. Then connect a real data source behind the same boundary, keeping execution simulated until approvals hold under load.
The AI does the investigating. People keep the authority. The space between them is designed, not left to chance.
Informative Nudge
Next